How “reverse game theory” could keep AI agents in check
A new approach known as “reverse game theory” aims to control powerful AI models by designing systems that incentivize them to stick to the rules.
As AI models become more capable, safety researchers are scrambling to ensure they are “aligned” with human desires—to make sure, in other words, that rogue agents don’t break the law, hack into unauthorized servers, or release poison gas into major cities and kill us all.
Until now, this work has mostly focused on trying to peer into an AI’s “brain” to understand what it is “thinking,” or training models to hew to values that we hold dear. Claude, for instance, has its constitution —a sort of moral code.
The trouble is, these techniques don’t seem to work particularly well: Models have been shown to deliberately underperform on tests, hide their intentions , and mislead their evaluators .
Now some alignment researchers believe that reverse game theory, also known as mechanism design, might get better results. Where game theory tries to predict how rational actors will behave when given a particular set of rules, reverse game theory attempts to design rules that will elicit the kinds of behavior we want to encourage.
An example of mechanism design in the real world might be the classic strategy for splitting a piece of cake in two: One person cuts the cake and the other gets the first choice of pieces. This incentivizes the cutter to make the pieces as even as possible. Other examples include surge pricing in ride-hailing apps, which encourages drivers to be available at busy times, and second-price auctions, where the winning bidder pays the price of the second-highest bid instead of the highest. Platforms use these auctions to sell online advertising because they encourage buyers to bid close to the maximum they are willing to pay.
In AI, mechanism design starts from the premise that we may never be able to understand enough about the internal workings of frontier models to make sure they are aligned. This means we should design mechanisms that incentivize agents to behave in ways that we want, regardless of what’s actually going on under the hood.
A recent preprint paper by Stephen Morris, an economist at MIT, along with colleagues from Yale and Columbia suggested some potential mechanisms that could stop agents from “sandbagging” tests (pretending to be worse than they actually are—for example, to avoid triggering safety mechanisms).
Instead of being rewarded only for how well it does on a test, a model could be rewarded for how well its answers predict what a second model will say. Deliberately playing dumb becomes a losing bet. “AI agents have a very good understanding of what other AI agents can achieve,” Morris says. “So it does seem like a context where this cross-checking could work more practically.
The paper also suggests pitting agents against each other, creating a competitive dynamic that incentivizes them to perform their best, or pairing agents that are known to be biased in opposite directions and rewarding them depending on how closely their outputs match, thus incentivizing them to reach an optimal answer.
A second approach, as envisioned by Elad Hazan, a professor of computer science at Princeton, is to design mechanisms that take inspiration from the ways human society keeps people “aligned”: social norms, the justice system, the monetary incentives of free-market capitalism. “We want to align superintelligent AI,” he says. “Why don’t we first talk about humans? How do we align humans?”
Hazan’s suggested mechanism involves having AI models take turns as either “solvers” that tackle problems or “auditors” that check the others’ work. “One agent acts like law enforcement; the other agent acts like the citizen,” he says.
During training, the models are rewarded depending on outcomes: Solvers that get caught cheating are punished, but so are auditors that fail to catch the cheaters. In situations where there’s a disagreement between auditors and solvers, the case can be sent to “trial”—perhaps a human expert will decide who is right.
There is, Hazan admits, a risk that agents will collude with each other—as auditors have colluded with the businesses they’re meant to be auditing, or corrupt police officers have colluded with criminals. But that problem can be solved by rewarding the auditors well enough, so that being caught isn’t worth the risk (a lot easier in the world of AI training than the real one, where money for police salaries is tight), and by auditing the auditors using techniques akin to employing mystery shoppers.
Hazan points to Nobel Prize–winning work by the economist Gary Becker, who introduced the idea of the “rational offender” in the 1960s. Criminals don’t break the law because they’re inherently bad people, he said. Instead, they do it when it’s the most rational choice given the incentives on offer. Crime makes sense only when the proceeds outweigh the potential punishment.
Alignment shouldn’t be thought of as a property of a model, he argues, but as a descriptor of its behavior at a particular moment. “You are, like, a nice person,” he says. “Are you aligned? I don’t know. Probably you are aligned most of the time, but there could be a situation where you’re not.”
One potential issue with applying mechanism design to AI: It relies on the assumption that AI agents behave rationally. Mechanism design has a mixed record with humans, who often fail to behave the way economic models say they should.
It’s ironic: Economists have spent decades trying to reduce human behavior to mathematics, and now, in large language models, we’ve built mathematical systems that run on human language and could be just as inscrutable. AI models exhibit behaviors that seem more human than machine, and they can be swayed by subtle factors that are difficult to understand and explain. “Is it even reasonable to assume that they will respond to incentives?” asks Helen Qu, a research fellow at the Flatiron…
Les actualités sont collectées automatiquement depuis des flux publics robotique & IA.
Articles liés
资本正在撤离“世界模型”
没有永远的夏天
After the midterms, things are looking rocky for Elon Musk and data centers
On Equity, we unpacked what the midterms mean for the tech industry.
Megaspeed exec was recruited to spy on Nvidia CEO, according to US intelligence memo
A memo circulated earlier this year reportedly claimed that China’s Ministry of State Security recruited a female technology executive to spy on Nvidia's CEO.
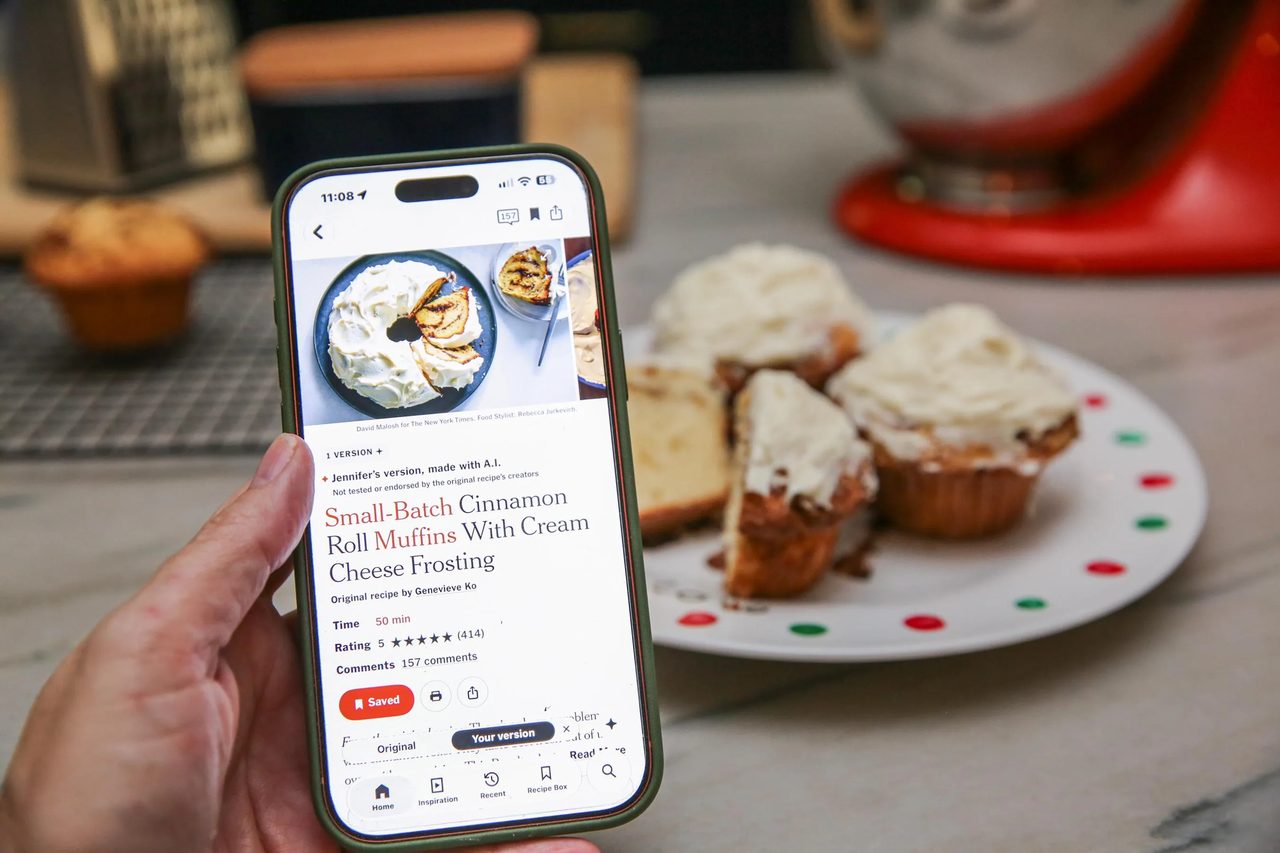
NYT Cooking’s AI assistant saved my weeknight chicken, but almost ruined my cake
Around 7PM each weeknight, I find myself standing in front of the fridge, trying to decide on something for dinner that won't make my husband complain, "Chicken again?" Yes, I should meal plan more, but I don't, so this is where I'm at. A nightly battle in which the chicken usually wins. Recently, m
The US let Nvidia sell chips to an empty office in China
Concerns are being raised that neither the Commerce Department nor Nvidia are doing their due diligence when it comes to vetting Chinese firms cleared to handle the company's H200 AI chips. According to The New York Times, New Matrix is on the list of approved firms, yet its offices are empty, "a ho
Apps for Caregivers Get a Dose of AI, but That Might Not Be Enough
The apps and platforms that help family caregivers manage their loved ones’ needs are becoming more capable, but the broader issue of caregivers’ well-being remains unsolved.